Get the full picture of your AI usage

Track AI usage, spend, performance, and every request across models, teams, and projects from one place.
‌200+ AI models
‌Logs and traces
‌Real-time cost tracking
‌EU-hosted
‌99.99% uptime
Observability hero mobile

Chosen by leading engineering teams

mobile logo carousel trusted white
waves bg observability

Observer

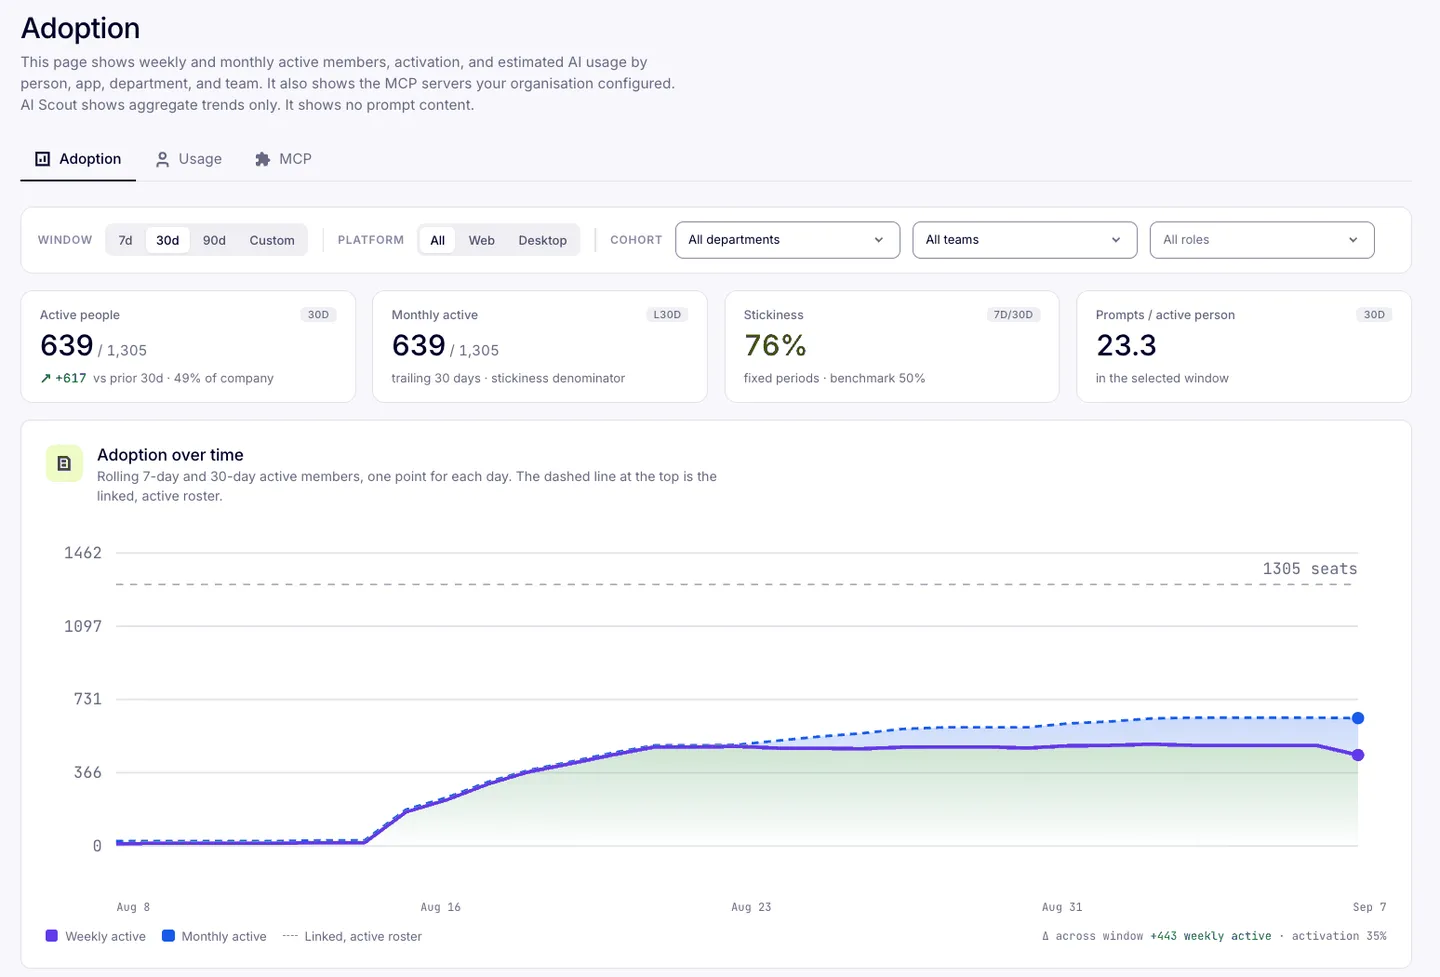
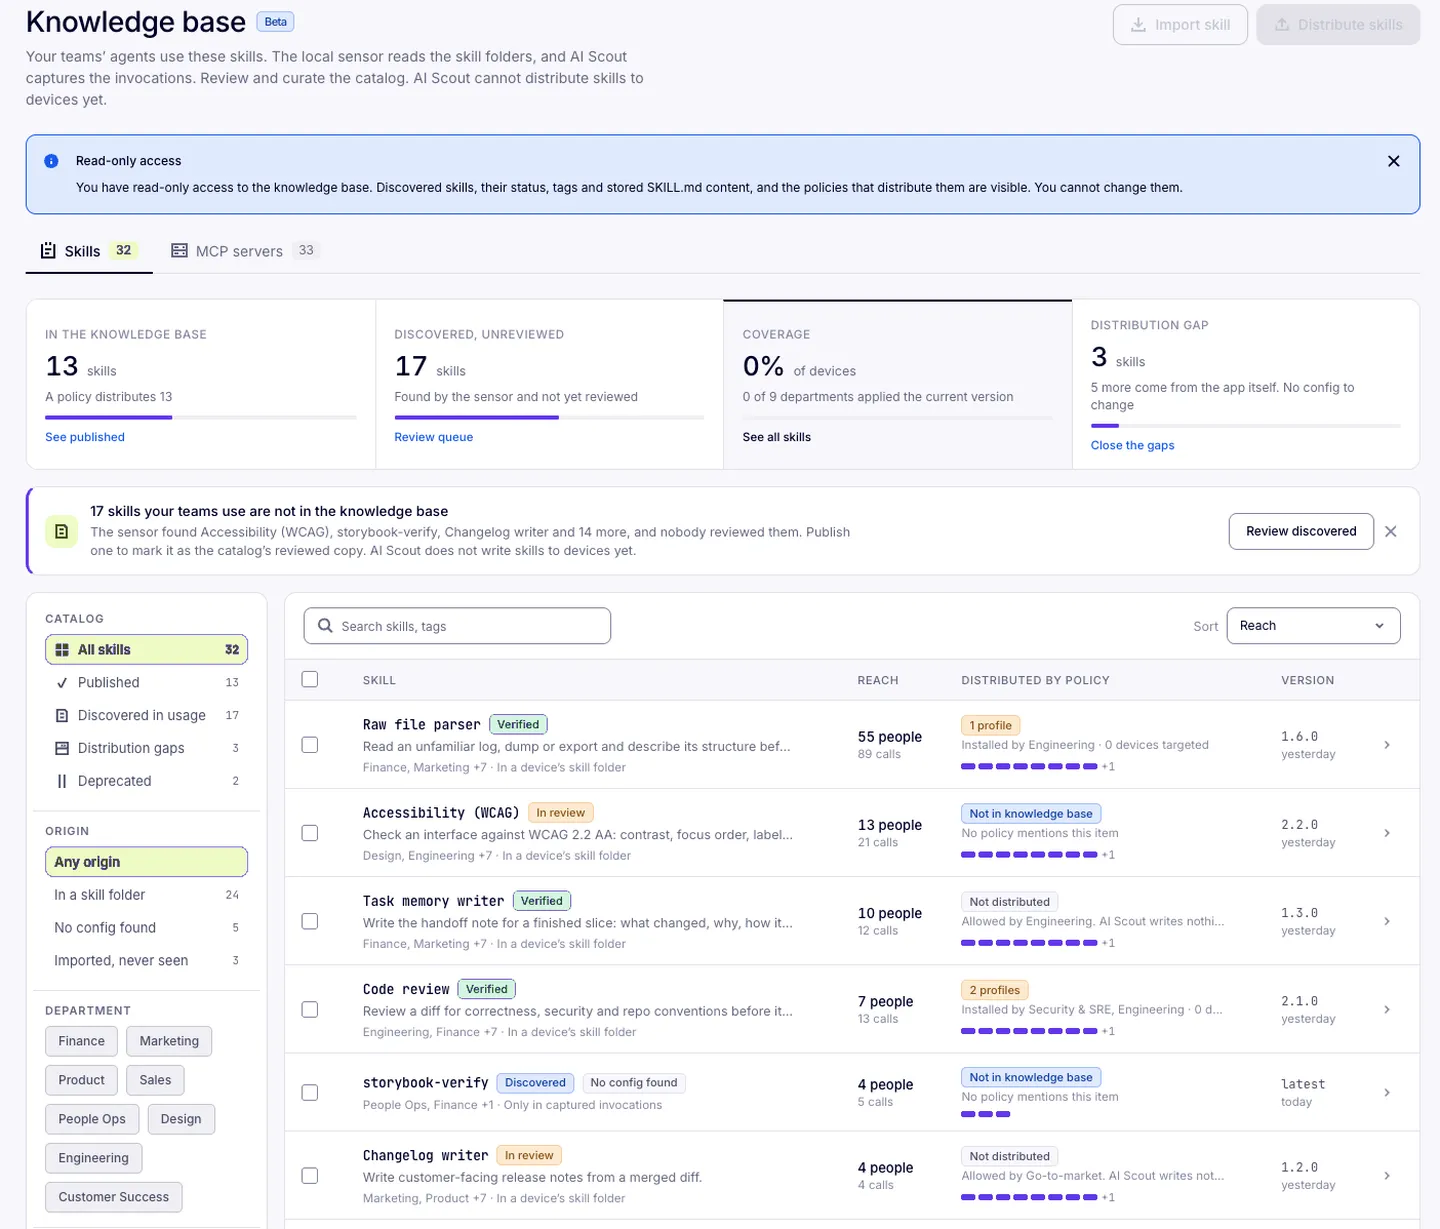
See how your organization uses AI

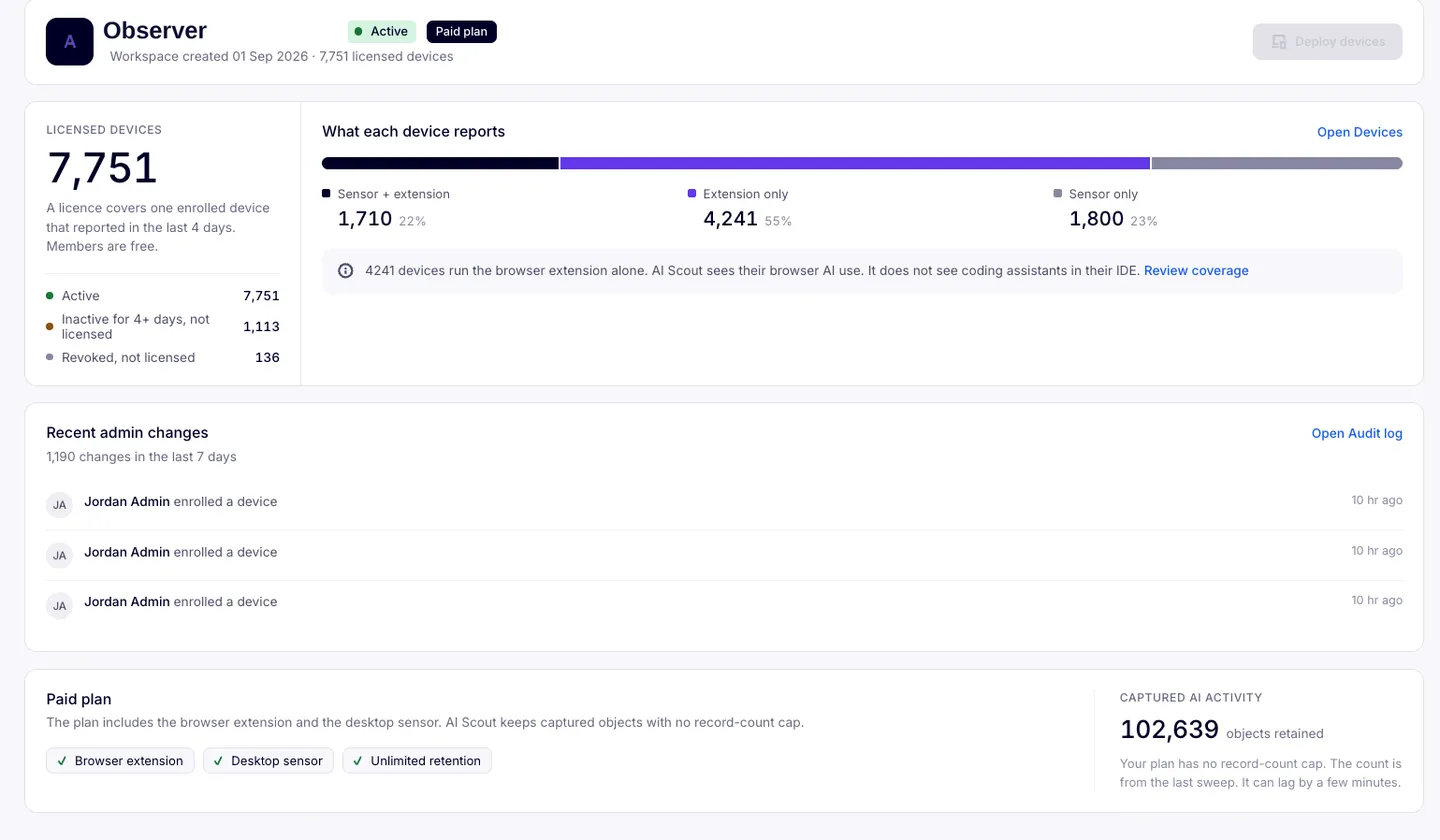
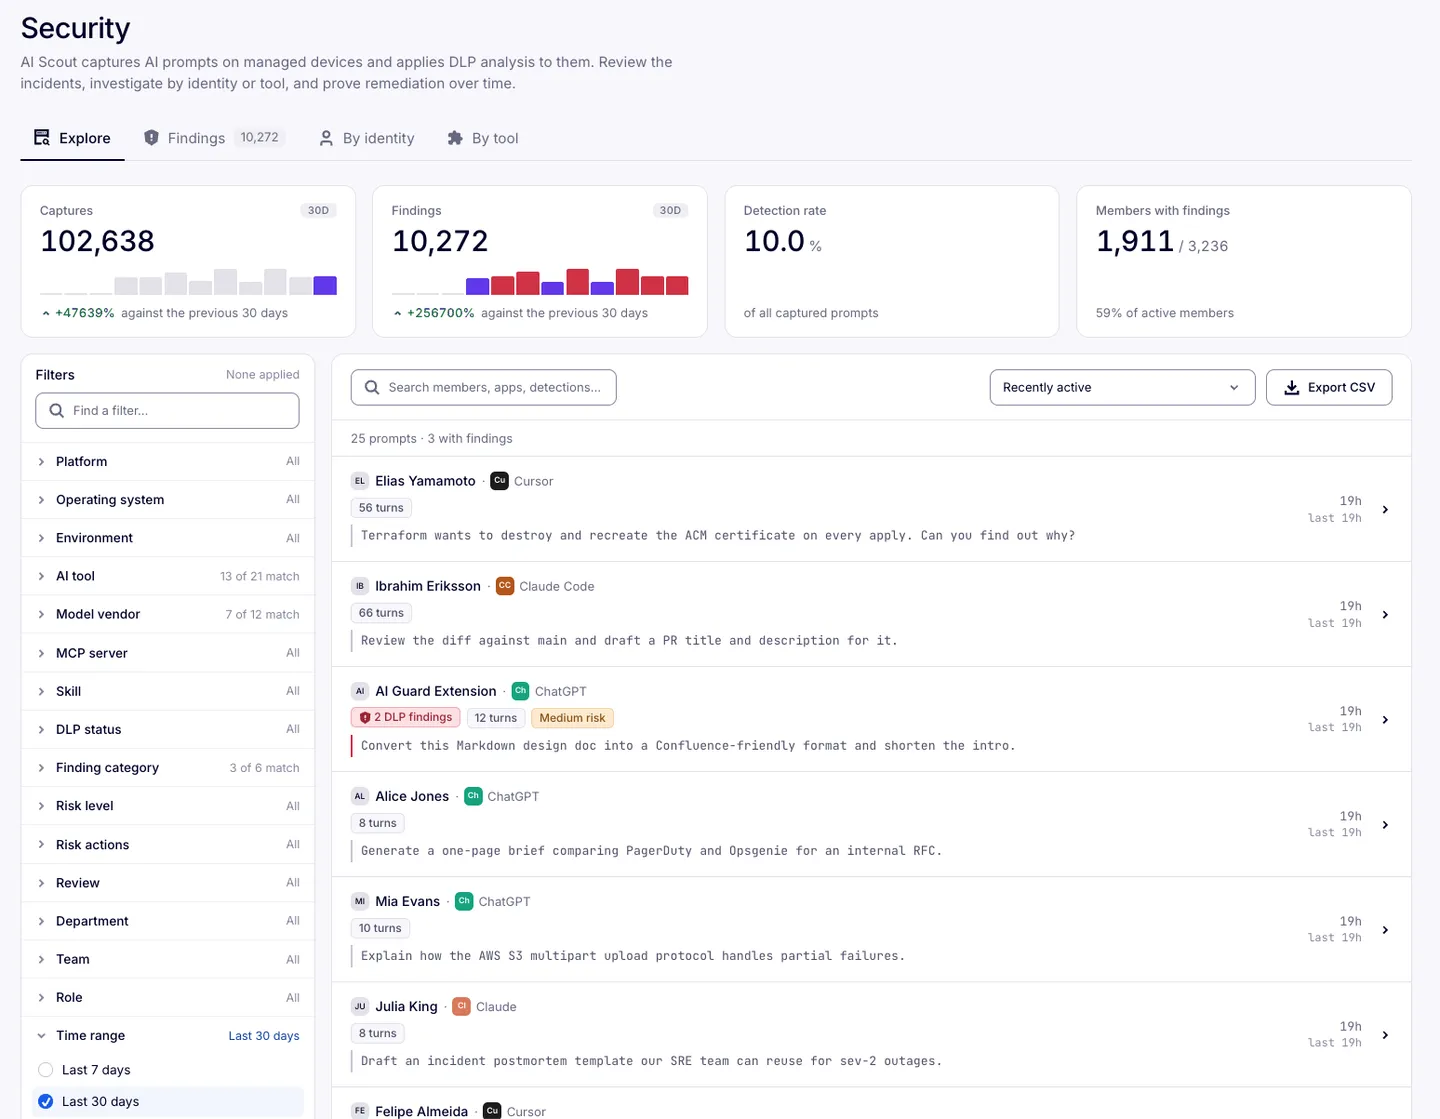
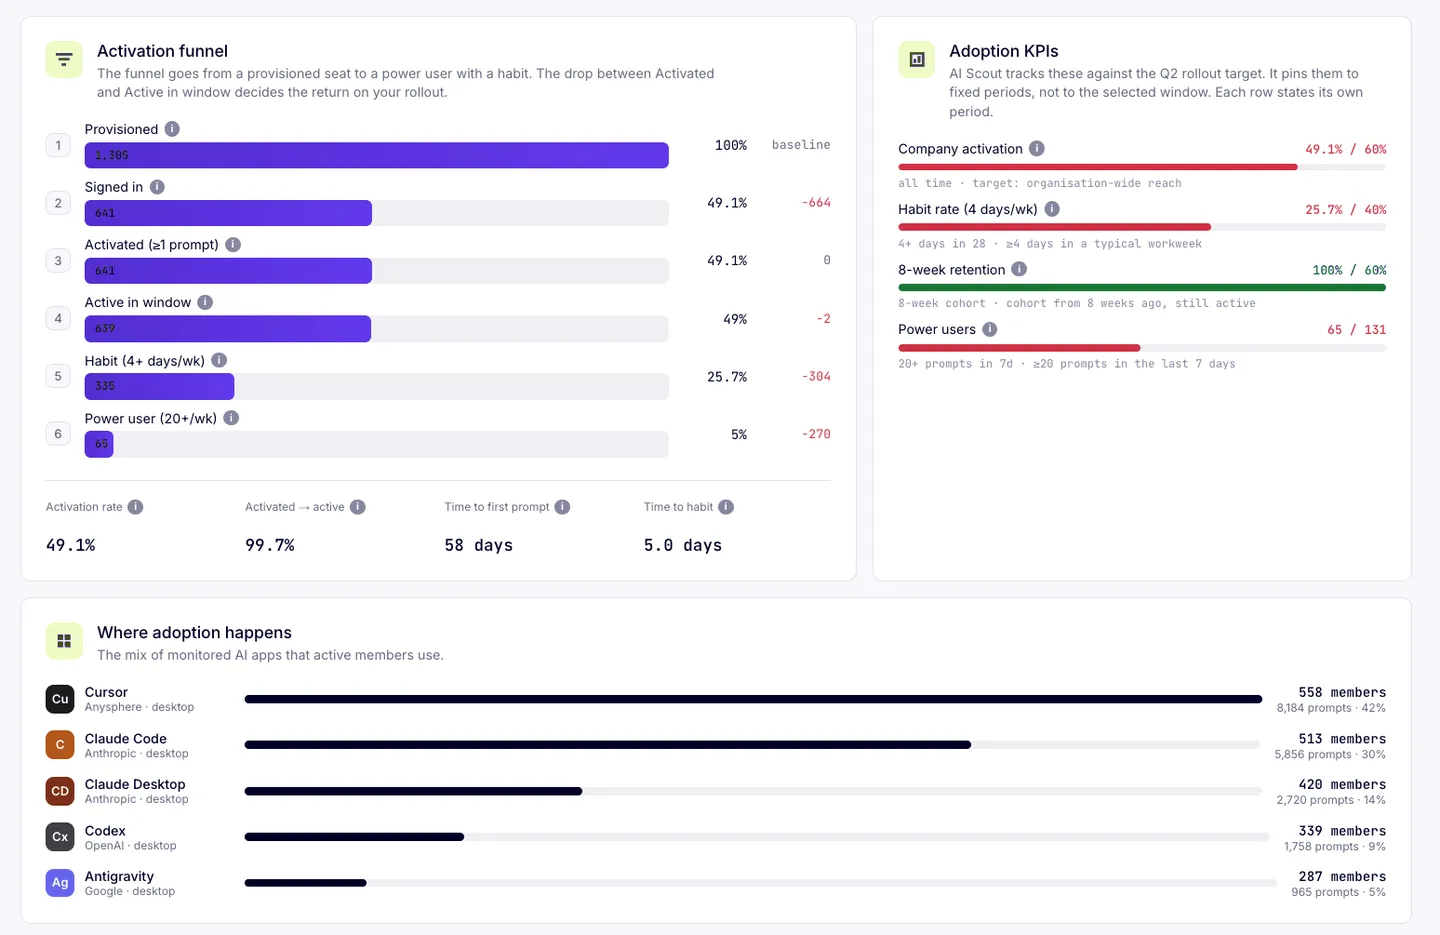
Per-tool AI usage chart showing Cursor, Claude Code, Codex, Antigravity and GPT with member counts and share of use
Findings by category donut chart with 1,994 findings split across secrets and credentials, financial data and personal identifiers
Active users and most-used app tiles above a usage breakdown list of teams by share of AI usage
Sensitive data in a prompt alert with a block action, above a recent findings table of members, apps and finding categories
Three-step onboarding cards: install across every device, set the policies, see full visibility instantly

From ChatGPT in the browser to Cursor and Claude Code on the desktop, all tracked.

Explore the platform

Observer
Observer

🔥 Early access

AI GATEWAY

Observe and manage LLM requests

nexos.ai gives you one place to monitor how AI is being used so you can optimize model choices, spend controls, and more.

Know what’s driving your AI spend

Provider invoices show you the total. nexos.ai helps you understand where it comes from.

Cost by application or workload
01
Track the cost of individual applications, agents, workflows, or internal tools using dedicated teams and API keys.
Cost by team or project
02
Understand how AI spend is distributed across your organization.
Cost by model
03
Compare usage and costs across models and providers.
Cost by request
04
See exactly what an individual request cost and how many tokens it consumed.
Budgets and limits
05
Set budgets and spend limits to keep growing AI usage predictable.

Observe and then optimize with nexos.ai Gateway

nexos.ai gives you visibility into your AI traffic and the tools to optimize how your AI runs.

Smart routing

Route requests based on cost, quality, latency and by task complexity, instead of sending every workload to the same model.

Caching

Avoid repeating identical requests to reduce latency and token usage.

Context compression

Reduce unnecessary tokens before requests reach the model.

Automatic fallbacks

Reroute requests when a model or provider becomes unavailable or experiences high latency.

Budgets and controls

Set budgets and limits across teams and users as AI usage grows.

200+ models through one endpoint

Access OpenAI, Anthropic, Gemini, Mistral, Moonshot AI (Kimi provider), and other leading models without maintaining separate integrations for each provider.

Keep your data secure with a European AI gateway

Protect sensitive AI workloads with European infrastructure, zero data retention, and built-in security controls.

No training on your data

Your data stays yours. It will never be used to train AI models unless you explicitly allow it.

Zero data retention

Enable Zero Data Retention (ZDR) for supported models to ensure prompts and responses aren't stored by the provider.

SSO and access controls

Secured access with SSO and RBAC to protect sensitive information.

Hosted in Europe

The nexos.ai platform and most of our available models are hosted in Europe. You can freely decide which LLM to use based on your preferences and compliance requirements.

Fully certified and secure

SOC 2 Type 2, ISO 27001 and ISO 42001-certified. Fully compliant with the GDPR.
GDPR badgeAICPA badge type2ISO badgeiso badge 42001

What engineering leaders say about nexos.ai

Get a clear view across your AI usage

Book a 30-minute technical demo to see how nexos.ai brings usage, spend, performance, logs, and traces across teams, models, and applications into one place.